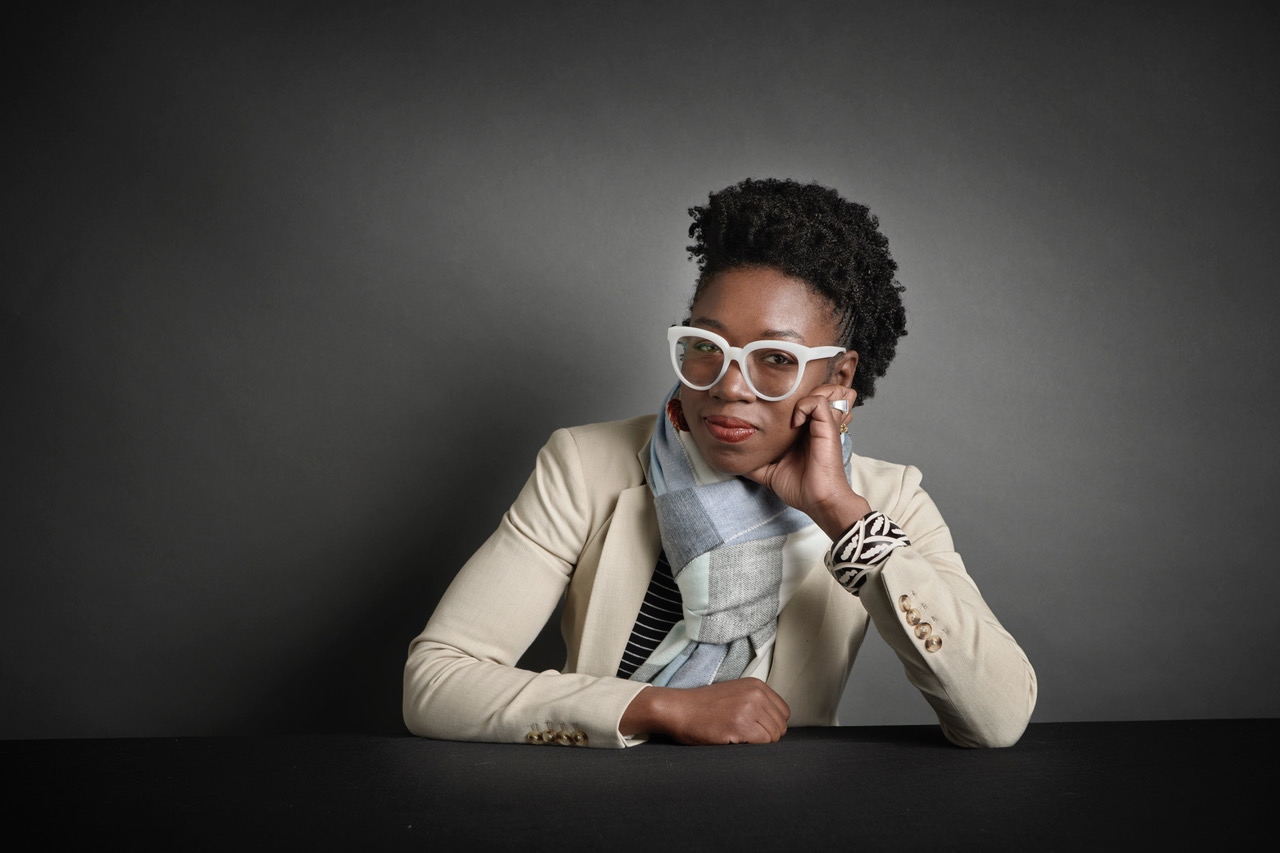
In 2015, Dr. Joy Buolamwini was working on an art project at MIT when facial-analysis software failed to detect her face. She put on a white mask. The software detected it. That incident stayed with her. Buolamwini began testing facial-analysis systems and asking why they worked differently across people.
Her research with computer scientist Timnit Gebru turned that question into evidence companies and policymakers could examine. The work did not solve AI bias. It changed the conversation around who gets to decide that a system is accurate, and what proof those claims require.
What Gender Shades measured
In 2018, Buolamwini and Gebru published Gender Shades, a study of three commercial gender-classification systems. The highest error rate for darker-skinned women reached 34.7%. For lighter-skinned men, the highest rate was 0.8%. These figures apply to the systems they tested and the task of classifying gender. They do not describe every facial-recognition product. The researchers also found that two widely used benchmarks contained far more lighter-skinned faces than darker-skinned ones. The study showed how the choice of test data can leave performance gaps hidden.
Personally, I have had to resort to literally wearing a white mask to have my face detected by some of this technology. — Joy Buolamwini,
For a company buying or selling facial technology, a good test result can be misleading if the test does not reflect the people who will encounter the product. A system may pass internal checks and still make more errors for some groups. That can become a costly problem when a customer uses it for identity checks, surveillance or access to services.
Buolamwini calls the human assumptions built into technology the “coded gaze.” People choose the data, define what the system should do and set the threshold for acceptable performance. Those decisions shape the product before a user ever sees it.
The study gave researchers and advocates specific questions to take to vendors: Which groups did you test? What errors did you measure? Does your benchmark resemble the people who will be affected? Those questions did not force companies to change their products, but they made general claims about accuracy easier to challenge.
Bringing the issue to lawmakers
Buolamwini founded the Algorithmic Justice League, an organization that combines research, advocacy and public education. It aims to give advocates evidence and draw attention to the people most affected by AI systems.
In 2019, Buolamwini testified before the U.S. Congress about facial recognition and civil rights. She raised concerns about the consequences of inaccurate systems in policing and called for stronger limits and oversight.
Mistaken identity is more than an inconvenience. — Joy Buolamwini
The distinction between facial analysis and facial recognition matters. Facial analysis classifies features or estimates attributes. Facial recognition compares faces to verify or identify someone. A wrong attribute classification and a false police match are different failures. The risks depend on what an organisation does with the result.
That last decision belongs to the buyer as well as the vendor. An agency chooses where to use the software, how much weight to give its output and whether someone can appeal. A technical error can have very different consequences depending on those choices.
Different systems, different risks
The National Institute of Standards and Technology tested 189 face-recognition algorithms from 99 developers in 2019. Its analysis used 18.27 million photographs of 8.49 million people. NIST found that demographic differences varied by algorithm and task. For some one-to-many searches, it reported higher false-positive rates for African American women.
A false positive occurs when a system wrongly identifies someone as a match. A false negative occurs when it misses a true match. Neither figure alone tells a buyer whether a product is suitable. A phone that fails to unlock and a police search that returns the wrong person call for different safeguards.
Several technology companies changed their policies in 2020. IBM said it would stop offering general-purpose facial-recognition and facial-analysis software. Microsoft said it would not sell facial-recognition technology to U.S. police departments until federal law grounded in human rights was in place. Amazon introduced a one-year moratorium on police use of Rekognition, then extended it indefinitely in 2021. The policies differed in scope; none created an industry-wide ban.
Researchers, employees, civil-rights advocates and lawmakers were all pressing companies at the time. Buolamwini’s work formed part of that wider pressure. The available evidence does not show that her research alone prompted each company’s decision.
The problem reaches beyond facial recognition
Automated decisions now appear in areas such as hiring, lending and health care. The technology changes, but a few practical questions remain: what is the system predicting, what data shaped it, and can a person learn why it reached a decision?
U.S. employment law applies when employers use software or AI to make or inform hiring decisions. The Equal Employment Opportunity Commission has explained how employers can assess whether a selection tool disproportionately excludes people in protected groups. This is existing civil-rights law being applied to new tools. It does not show that Buolamwini’s work directly produced the guidance.
The Consumer Financial Protection Bureau has made a similar point about lending. Lenders must give applicants specific reasons when they deny credit, even when a complex algorithm makes those reasons hard to identify. The model’s complexity does not remove the lender’s obligation to explain its decision.
Health care provides a striking example of how a system can predict the wrong thing. Researchers studied an algorithm that used expected health-care costs to estimate patients’ need for extra care. Because the health system spent less on Black patients than on equally ill white patients, the algorithm assigned lower risk scores to many Black patients. The study estimated that correcting the bias would raise the share of Black patients identified for additional care from 17.7% to 46.5%. The system predicted spending, but spending was a poor measure of medical need.
That distinction has direct consequences for people. An automated decision can affect whether someone gets an interview, a loan or additional medical support. Companies may gain speed or reduce costs through automation. They still choose the data, the goal and how much influence the system has over a person’s options.
What regulation can require
Research can expose a failure. It cannot ensure that every company publishes test results or that every person harmed by an automated decision receives a remedy.
Washington state’s 2020 facial-recognition law sets requirements for government agencies using the technology. Agencies must prepare accountability reports and consult the public. The law also requires meaningful human review for certain significant decisions and provides for independent testing of performance differences. Its reach is limited to government use in Washington; it does not regulate every private use or every kind of AI.
There is no single technical fix for algorithmic discrimination. A system can fail because its data are unbalanced, its target is a poor proxy or its buyer uses it in a setting the developers did not test. Regular evaluation helps only when someone responds to the results. People affected by important decisions also need a way to question them.
Buolamwini’s research did not remove bias from AI. It helped make one set of failures measurable and harder to dismiss. Her influence lies in that shift, from a user’s complaint to evidence that companies and policymakers had to address. Whether AI systems improve will depend on what their builders and buyers do with that evidence.
FAQs
What did Joy Buolamwini find?
Facial-analysis software failed to detect Buolamwini’s face during an MIT art project until she wore a white mask. Her later research documented accuracy gaps across skin-tone and gender groups.
What did Gender Shades show?
The 2018 study tested three commercial gender-classification systems. Error rates reached 34.7% for darker-skinned women and 0.8% for lighter-skinned men in the systems tested.
Are facial analysis and facial recognition the same?
No. Facial analysis classifies or estimates facial attributes. Facial recognition compares faces to verify or identify someone. Their errors can have different consequences.